


Zillow and Realtor.com don't offer public APIs, which is exactly why scraping is still the standard way to track listings, pricing, and market trends at scale. Here's how to do it without crossing into legal or technical trouble: the compliance rules, where the real data actually lives, and how to scale past the block wall.
Scraping publicly accessible data (no login, no paywall) with ethically sourced proxies isn’t a violation of the Computer Fraud and Abuse Act. The Ninth Circuit held as much in hiQ Labs v. LinkedIn in 2022. It’s likely a breach of the platform's Terms of Use, which is a civil matter rather than a criminal one.
That distinction is the whole legal picture in one sentence, and the hiQ case itself demonstrates both halves. hiQ won on the CFAA question and then lost on the contract question: the court found it had breached LinkedIn's user agreement, and the case ended with an injunction against hiQ. Winning the criminal-statute argument didn't save the company. The case is often cited as a clean green light for scrapers, which it isn't.
Four rules follow from that:
This is informational, not legal counsel. A commercial project against a major portal warrants actual legal advice before it runs.
Real estate portals are mostly single-page applications, which means the listings you see on screen aren't sitting in the HTML your scraper receives. They arrive afterward, loaded by background network requests as the page renders.
Parsing the rendered HTML with something like BeautifulSoup means fighting a moving target every time the site adjusts its layout – and portals adjust constantly. The more durable approach is to find the data before it becomes HTML.
Open dev tools, watch the Network tab, and filter for XHR or fetch requests around "search" or "listings." That's usually the raw JSON payload the front end is consuming, and it's both cleaner and more stable than anything you'd reconstruct from the DOM. Some portals also embed structured data directly in the page source: a JSON-LD block (<script type=" application/ld+json">) or a state-hydration block such as __NEXT_DATA__.
A handful of open-source libraries already map these endpoints for specific platforms, which is worth checking before writing a parser from scratch.
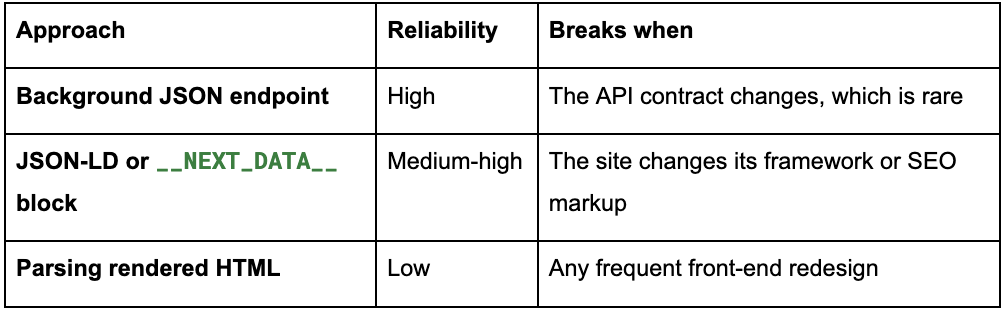
There's a certain irony in scraping portals that built their own inventory by aggregating MLS feeds, but the practical point stands: go where the structure already is.
Scrape real estate listings from a single IP at any real volume, and you'll hit a CAPTCHA or a hard block within minutes. These platforms are built to expect exactly this and resist it.
The standard fix is routing requests through a proxy layer built for the job: rotating residential IPs instead of a flagged data center range, paired with realistic browser headers. Residential IPs route through real devices on real ISPs, so a request looks like a genuine property search rather than a server in us-east-1. This can lower block rates compared to datacenter IPs, though success still depends on the target's defenses, your request pattern, and your rotation settings.
GoProxies' scraping API handles the rotation, JavaScript rendering, and CAPTCHA solving as one endpoint, with real estate structured data as a named use case. The underlying pool is 30M+ rotating residential proxies across 200+ locations, which is the geographic spread that regional listing coverage needs.
Before writing any of it, define the data contract. Three fields decide whether your dataset is usable six months in:
1. Find the data source: Open dev tools on a search results page, filter the Network tab to XHR or Fetch, and look for the request returning listing objects. Copy it as cURL to see exactly which headers and parameters the site sends.
2. Route the request through a proxy: Send your version of that request through a proxy-routed endpoint rather than your own IP, with headers matching what a real browser sends – including an Accept-Language value consistent with the market you're querying.
Credentials come from the environment rather than the source file, and raise_for_status() means a 403 surfaces immediately instead of turning into a confusing parse error three lines later.
3. Parse into a defined schema: Map the response onto your data contract: MLS ID, address, ZIP code, latitude and longitude, price, status, days on market. Define the schema before the first run, not after the third.
4. Deduplicate on ingest: Match against your existing dataset by permalink or MLS ID before writing. Listings cross-list across portals constantly, and deduplicating after the fact is far harder than refusing the duplicate at the door.
5. Schedule a refresh: Daily or weekly, not continuous polling. Set it as a scheduled job with logging, so a silent failure shows up as a missing run rather than a quietly stale dataset.
Real estate listings cross-list across platforms constantly, so aggressive deduplication against a stable identifier matters more here than in most scraping use cases. The same property can appear on four portals with four different listing IDs, three different photo sets, and two different prices – deduplicate on MLS ID or normalized physical address, not on whatever the portal calls its own record.
Refresh cadence is the other half. Unlike e-commerce pricing or stock levels, real estate inventory moves slowly. A daily or weekly pull captures essentially everything that changed, and scraping hourly just adds load on the source for no additional signal. Pair that with price monitoring at scale patterns if you're tracking price movements specifically, since the change-detection logic is the same problem.
Gintarė specializes in content related to proxies, web scraping, data collection, and internet infrastructure. With a solid background in information technology, networking, and cybersecurity, she understands both the technical and practical aspects of large-scale data acquisition.
The rich text element allows you to create and format headings, paragraphs, blockquotes, images, and video all in one place instead of having to add and format them individually. Just double-click and easily create content.
A rich text element can be used with static or dynamic content. For static content, just drop it into any page and begin editing. For dynamic content, add a rich text field to any collection and then connect a rich text element to that field in the settings panel. Voila!
Headings, paragraphs, blockquotes, figures, images, and figure captions can all be styled after a class is added to the rich text element using the "When inside of" nested selector system.


Scraping publicly accessible data isn't a CFAA violation under current precedent. It's very likely still a breach of the platform's Terms of Use, which is a civil matter. Never copy photos, agent bios, or full listing descriptions – those are copyrighted creative work even when the underlying facts aren't.
Real estate platforms actively defend against exactly this, and a single IP making real volume gets rate-limited or CAPTCHA'd within minutes. Routing requests through rotating residential proxies rather than a flagged data center range is the standard fix at scale.
Target the JSON. Most portals are single-page apps that load listings via background network requests or embed them in a __NEXT_DATA__ or JSON-LD block. Parsing rendered HTML means rebuilding your scraper after every layout change.
Yes. Real estate structured data is a named use case for GoProxies' scraping API, which handles JavaScript rendering, IP rotation, and CAPTCHA solving, with city-level geo-targeting across 200+ locations.


